Inkling 2 Mini uses looped layers to reason locally
Thinking Machines has released Inkling 2 Mini, an open mixture-of-experts model that uses looped layers to think internally before generating text.
2 min read, Saturday, 21 November
Thinking Machines has released Inkling 2 Mini, an open-source artificial intelligence model designed to reason more deeply before responding. The system uses a looped transformer architecture, which means it runs certain layers multiple times for each token of text. Specifically, Inkling 2 Mini passes data through 12 of its 24 layers three times in a row. This internal loop lets the model spend more time working through complex problems without generating excessive output text, allowing it to find correct answers using fewer tokens.
Key facts
- Total parameters
- 26.4 billion
- Active parameters
- 5.4 billion
- Context window
- 1 million tokens
- License
- Apache 2.0
- DeepSWE v1.1 score
- 48.2 percent
- Intelligence Index score
- 20
- Intelligence Index
- Inkling 2 Mini: 20
- Qwen3.8 27B: 20
- Nanbeige4.3-33B: 20
- Total parameters
- Inkling 2 Mini: 26.4 billion
- Qwen3.8 27B: —
- Nanbeige4.3-33B: —
- Active parameters
- Inkling 2 Mini: 5.4 billion
- Qwen3.8 27B: —
- Nanbeige4.3-33B: —
| Metric | Inkling 2 Mini | Qwen3.8 27B | Nanbeige4.3-33B |
|---|---|---|---|
| Intelligence Index | 20 | 20 | 20 |
| Total parameters | 26.4 billion | — | — |
| Active parameters | 5.4 billion | — | — |
Architecture and Performance
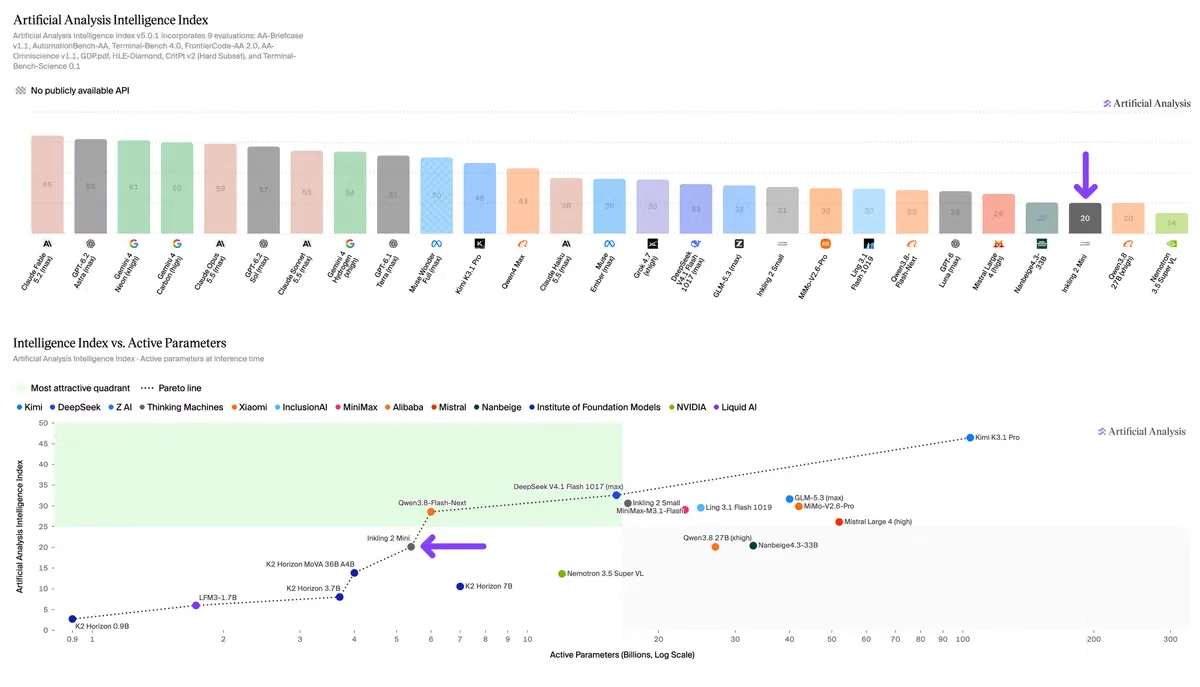
The open mixture-of-experts model — a design where only a subset of sub-networks activate for any given input — contains 26.4 billion total parameters. Because of the looping mechanism, only 5.4 billion parameters are active per token. The model handles both text and images, and it includes a 1-million-token context window to process large documents or codebases. It is released under the Apache 2.0 license.
On agentic coding tests designed to measure a model's ability to solve software development tasks autonomously, Inkling 2 Mini leads all open models with fewer than 100 billion parameters. It scores 48.2 percent on DeepSWE v1.1 and 46.5 percent on the Vals Index v2.2. Independent evaluations by Artificial Analysis assign the model 20 points on its Intelligence Index, placing it on par with Qwen3.8 27B and Nanbeige4.3-33B while operating at lower cost and higher speed.
Running Locally
Developers can run Inkling 2 Mini locally on Apple computers equipped with at least 32 gigabytes of memory, as well as on Nvidia hardware such as the DGX Spark. The model weights and a research version that supports variable loop counts are available on Hugging Face. Users who want to test the model without a local setup can also try it directly in the Tinker Playground.
Source: Original announcement
Worth a read?
Comments