Gemini 3.8 Live and Live Extended Thinking release
Google has released Gemini 3.8 Live and Gemini 3.8 Live Extended Thinking, two advanced voice dialogue models designed for natural, fluid conversations. The models support real-time visual grounding, background tool execution, and multi-step reasoning.
Published by Jin · 2 min read · 16 SEPT 2026
- StepAudio 3 Realtime (99.7%)
- StepAudio 3 Realtime (98.9%)
- Deepslate Opal (0.44s)
- Qwen Audio 3.0 Realtime Plus ($0.0331/hour)
| Metric | Model | Big Bench Audio Score |
|---|---|---|
| StepAudio 3 Realtime | StepAudio 3 Realtime | 99.7% |
| Qwen Audio 3.0 Realtime Plus | Qwen Audio 3.0 Realtime Plus | 99.2% |
| Qwen3.5 Omni Plus Realtime | Qwen3.5 Omni Plus Realtime | 98.7% |
| Gemini 3.8 Live Extended Thinking (High) | Gemini 3.8 Live Extended Thinking (High) |
Google has introduced two advanced voice dialogue models, Gemini 3.8 Live and Gemini 3.8 Live Extended Thinking, designed to make voice interactions more natural, fluid, and intuitive.
Overview of the New Models
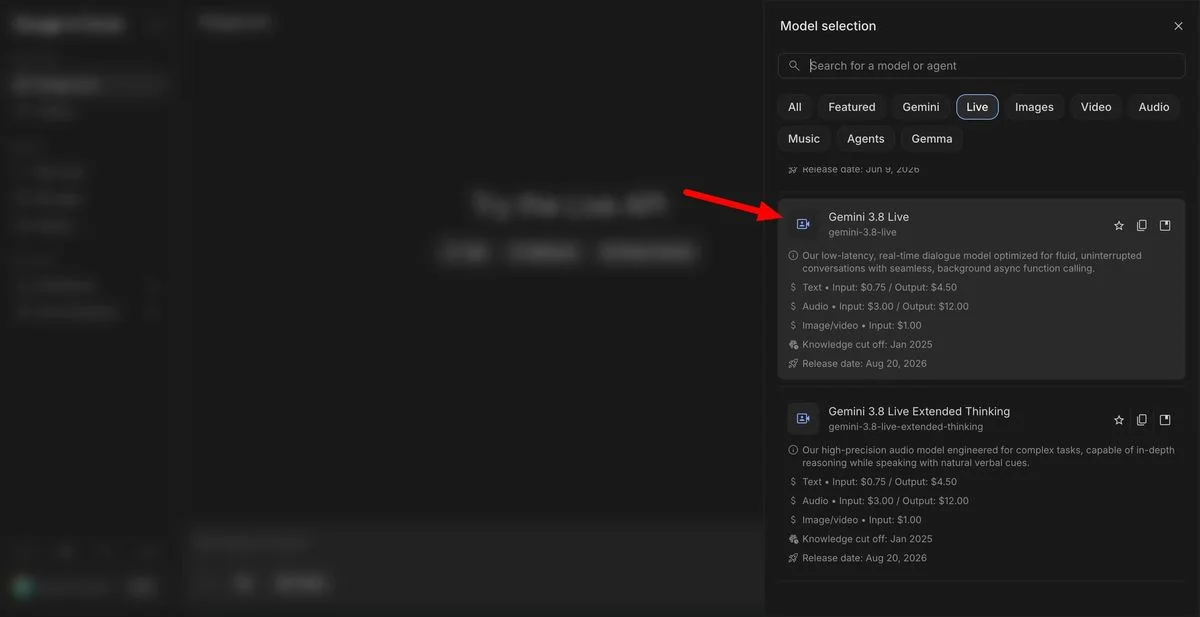
The standard Gemini 3.8 Live model is built for scale and cost efficiency, combining conversational intelligence with real-time visual grounding. It can process visual inputs in near real-time and automatically detect and switch between 97 supported languages mid-conversation.
Gemini 3.8 Live Extended Thinking is designed for high-complexity tasks, offering increased intelligence and multi-step reasoning while maintaining an uninterrupted conversational flow. It can reason and speak simultaneously, using early verbal cues to acknowledge prompts and live progress narration to walk users through background tasks.
Capabilities and Performance
Both models can execute tools and API calls in the background while keeping the conversation going. Gemini 3.8 Live Extended Thinking captures the top spot on Artificial Analysis' Speech to Speech Quality Index with a score of 82.6. It also leads in agentic task completion with 68.6% on the τ-Voice benchmark and 35.1% on Sierra's τ-Voice-banking benchmark, alongside scoring 97.7% on Big Bench Audio.
To help prevent misinformation, all audio generated by these products includes SynthID watermarking woven directly into the audio output.
Availability
Developers can access both models through the Gemini API and Google AI Studio, with support from developer platforms such as Agora, Fishjam, LangChain, LiveKit, Pipecat, Vercel, and Vision Agents. Enterprise users can find them in private preview in Gemini Enterprise, while general users can access them across Search Live, Google Workspace, and the Gemini app.
Source — Original announcement ↗
Worth a read?
Comments · 0