Alibaba launches Qwen4-Max with hybrid architecture and lower costs
Alibaba has released Qwen4-Max, a 2.4-trillion-parameter mixture-of-experts model designed for efficient long-context processing and autonomous agent tasks.
2 min read, Tuesday, 17 November
Alibaba has introduced Qwen4-Max, a new flagship artificial intelligence model designed to handle complex professional work in industry, science, and finance. The model features a hybrid architecture intended to process long texts more efficiently and at a lower cost than previous generations.
Key facts
- Total parameters
- 2.4 trillion
- Active parameters
- 71 billion
- Context window
- 1 million tokens
- Input price
- $1.50 per 1M tokens
- Output price
- $4.50 per 1M tokens
- Cache hit price
- $0.075
- Intelligence Index Score
- Qwen4-Max: 43
- Qwen3.8-Max: 34
- Kimi K3.1 Pro: 46
- Tencent Hy4: 35
- Cost per Task
- Qwen4-Max: $3.27
- Qwen3.8-Max: $10.02
- Kimi K3.1 Pro: $3.68
- Tencent Hy4: $1.03
- Total Parameters
- Qwen4-Max: 2.4 trillion
- Qwen3.8-Max: 2.4 trillion
- Kimi K3.1 Pro: 2.8 trillion
- Tencent Hy4: —
| Metric | Qwen4-Max | Qwen3.8-Max | Kimi K3.1 Pro | Tencent Hy4 |
|---|---|---|---|---|
| Intelligence Index Score | 43 | 34 | 46 | 35 |
| Cost per Task | $3.27 | $10.02 | $3.68 | $1.03 |
| Total Parameters | 2.4 trillion | 2.4 trillion | 2.8 trillion | — |
Architecture and efficiency
Qwen4-Max is a mixture-of-experts model — an architecture where the model routes each input token to specialized sub-networks rather than using the entire network at once. The model contains 2.4 trillion total parameters, with 71 billion active per token. It processes images natively and includes a one-million-token context window.
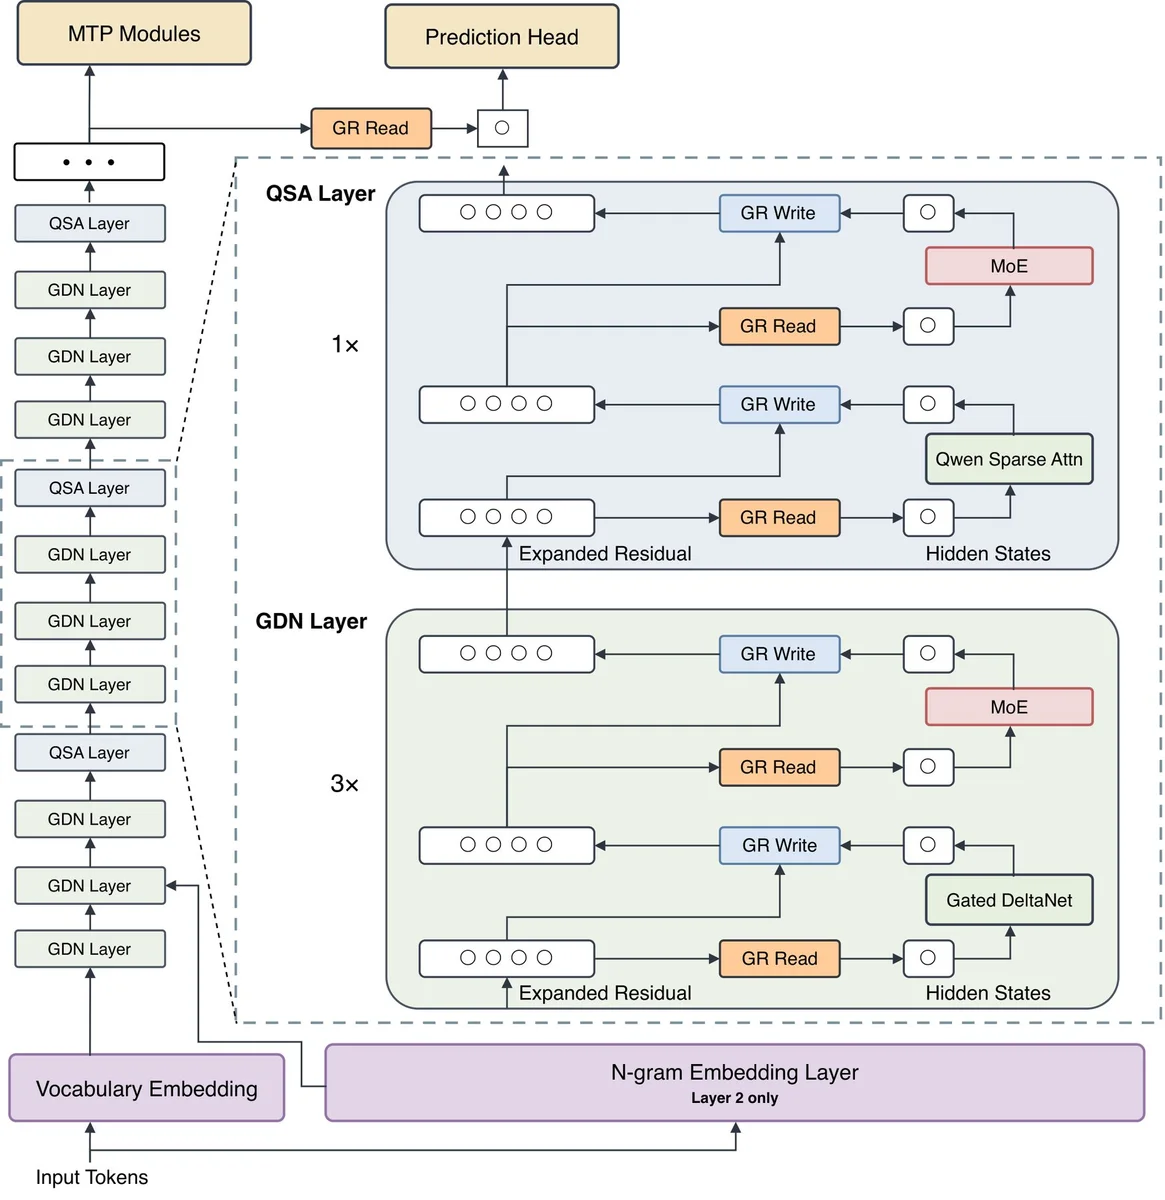
To reduce the high computational cost of long inputs, the model uses a hybrid attention design. Three layers compress prior context into a condensed state, and a fourth layer selects only the relevant parts. This approach lowers compute costs because the model does not need to give every part of the context equal attention. An N-gram embedding layer with 328 billion parameters supplies common token sequences as ready-made building blocks.
Benchmarks and operating costs
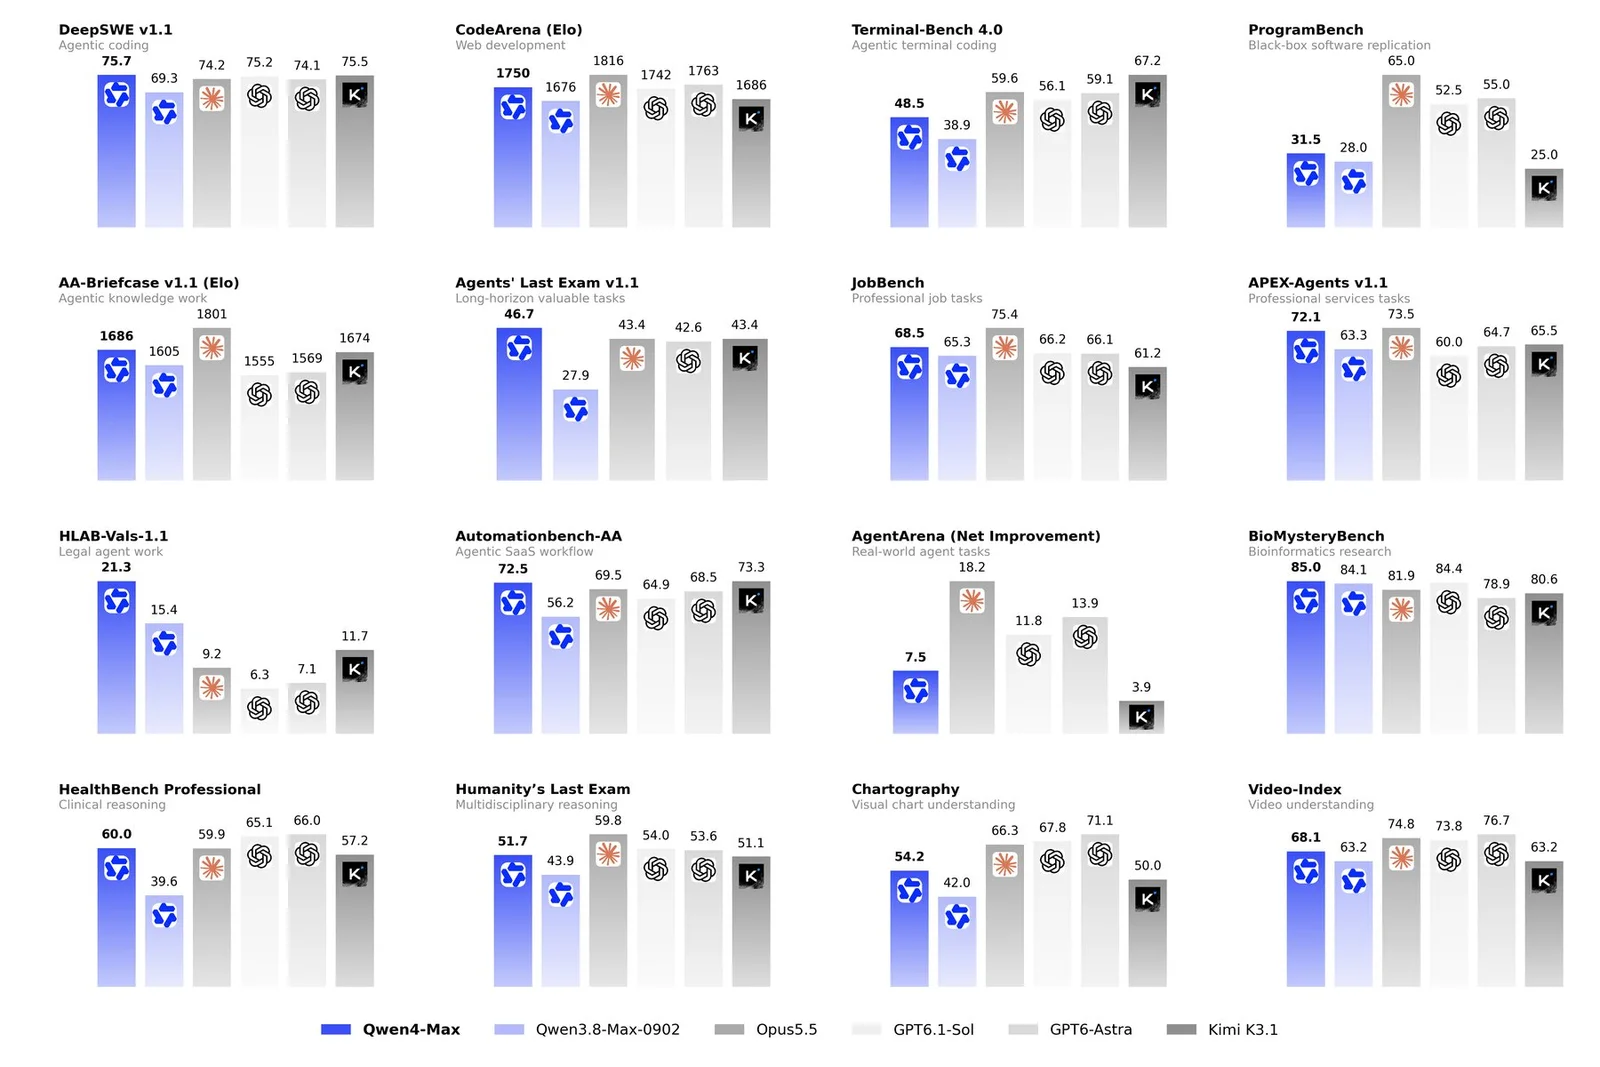
On the Artificial Analysis Intelligence Index, Qwen4-Max ranks second among Chinese models behind Kimi K3.1 Pro, scoring 43 points at its highest reasoning setting. Operating costs are lower than its predecessor, with Artificial Analysis estimating the cost at $3.27 per index task, down from $10.02 for Qwen3.8-Max. Alibaba charges $1.50 per million input tokens and $4.50 per million output tokens through its API, with cache hits costing $0.075.
Agent capabilities and tools
The release includes a feature called Live Delivery, which allows users to inspect intermediate results from autonomous agents early and adjust running tasks on the fly. Alibaba has open-sourced the accompanying Qwen-Live-Delivery-Plugin. In practical demonstrations, the model has been paired with automated lab systems to synthesize chip coolants and design candidate drug molecules, and it can generate playable games and 3D models from natural-language descriptions.
Source: Original announcement
Worth a read?
Comments