Lesson 21
Keeping scores calm
Build an LLM From Scratch, 53 lessons
Lesson 21: Keeping scores calm
Build an LLM From Scratch, Lesson 21 of 53
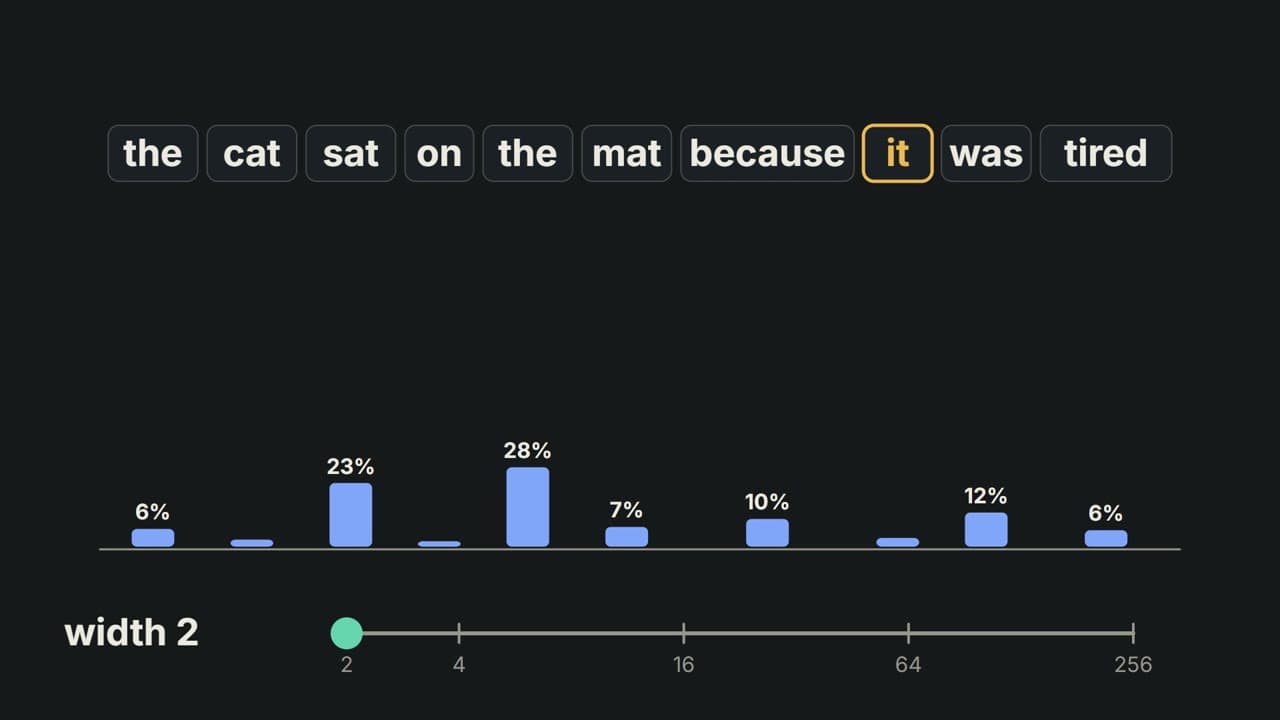
Wider random queries and keys spread scores further apart. Softmax can then put nearly everything on one word and respond weakly to training. Dividing by the square root of the width keeps the starting spread calm.
The question for this lesson: why do big scores break attention, and why divide by the square root of the width?
Last lesson made each score from a query and a key: multiply matching numbers, then add. In its pictures a query and a key were 2 numbers wide, so a score added up 2 products. In GPT-2 small they are 64 numbers wide, so a score adds up 64 products.
A head is one set of queries, keys and values doing this job; lesson 23 will use several side by side.
That left a worry. With wide vectors, random scores can spread far apart. Why can that break attention?
The rest of this lesson is in Premium
Premium includes every lesson, with its notes, practice and progress.